Rocío Belfiore is Chief Innovation Officer at BairesDev, where she leads teams developing internal software projects that propel company growth. She has been with BairesDev for over 11 years, advancing through engineering and R&D leadership roles.
Expertise


Data only changes a decision when someone can explain it clearly. Before the full breakdown, here is what engineering and data leaders need to know.
Key Points
- Your model’s accuracy means nothing if stakeholders can’t understand the finding well enough to act on it.
- Python and SQL are the baseline pair your team needs. R adds value only when your work is heavily statistical or research-oriented.
- Effective data storytelling gives decision makers enough context to understand what the data says, how reliable it is, and what action it supports.
- Complex machine learning models can be difficult to explain. Explainable AI provides practical approaches for improving transparency and helping teams build confidence in, evaluate, and challenge model outputs.
- Presenting methodology and limitations explicitly is what earns stakeholder trust. Hiding them to simplify the story undermines the result.
Speaking data science means turning data, analysis, and model output into stories that clearly explain what matters, how confident you should be, and what decision the evidence supports. For engineering leaders, that means combining sound analysis with audience-aware storytelling, useful visualizations, transparent methodology, and explicit limits. The goal is to make the science usable.
Data science as a distinct discipline is a relatively new field, but it draws on decades of work in computer science, statistics, mathematics, and data analysis. Today, data scientists clean and manipulate data, perform statistical analysis, build machine learning models, visualize findings and insights, and increasingly work with artificial intelligence systems.
The technical toolkit matters, but technical knowledge alone does not guarantee impact. You can have a highly accurate model and still struggle to get a product manager, an executive, or a customer-facing team to act on its findings.
Communication belongs alongside programming, statistics, and machine learning in the modern data science skill set.
The hardest part of data science is rarely the model; it is getting the rest of the business to act on what the model says. That is why data teams who turn Python pipelines into decisions executives actually trust treat communication as a first-class deliverable, not an afterthought. A clean heat map and an honest methodology note often move a decision faster than another point of accuracy ever could.
What Does It Really Mean to Be Data Driven?
Being data driven means using relevant evidence as a primary input into decision making rather than relying on intuition, assumptions, or organizational habit alone.
Experience still matters. Experienced engineers, product managers, and executives often recognize patterns that a data set cannot capture, and that recognition typically develops over the course of years working in a domain. The goal is to combine that judgment with evidence rather than allowing either one to operate in isolation.
A data-driven approach usually depends on three things:
- Reliable data: The underlying data needs to be accurate enough, timely enough, and relevant to the question being asked.
- Useful analysis: Teams need to identify patterns, relationships, anomalies, and potential implications rather than simply collecting more data.
- A path to action: Findings need to connect to a decision, experiment, product change, operational adjustment, or other measurable outcome.
Data can come from many sources, including customer feedback, surveys, website analytics, application telemetry, transaction records, social platforms, and internal systems.
Collecting all the data available isn’t the point; a lot of what looks like signal turns out to be noise. Pick the data that answers the question that matters.
A data-driven culture also means making data analysis a shared capability rather than isolating it inside a data science team. Engineers, product managers, analysts, and decision makers need enough shared understanding to question assumptions, talk through findings, and recognize when further analysis is necessary.
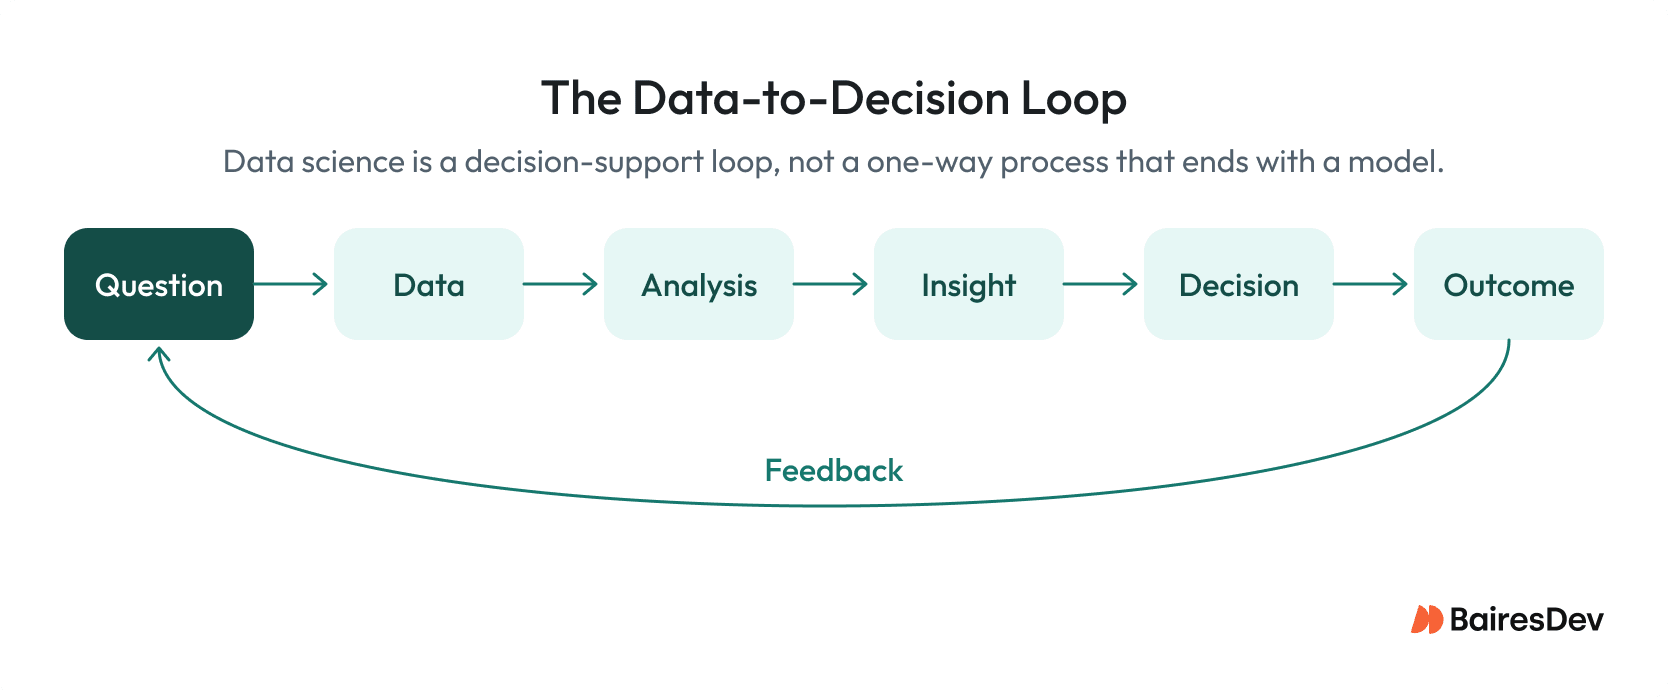
Why Should You Tell a Story Instead of Reciting Numbers?
Numbers rarely speak for themselves. A data scientist can present a statistically significant result and still leave an audience wondering what it means, and a data analyst can share a dashboard containing a lot of metrics without making the most important finding obvious.
Data storytelling works by giving the audience a structure that helps people understand the analysis. Useful data stories generally answer four questions:
- What happened?
- Why does it matter?
- How confident are we in the finding?
- What should happen next?
The story doesn’t need to hide complexity; it is about giving readers a way to engage with complexity by putting it in the right place.
For example, instead of telling an executive that a customer segment has a higher conversion rate, which is easy to talk past without context, explain what that difference means for the business, how the segment was identified, whether the result is statistically and practically meaningful, and what decision the team could make as a result.
Engineers are a different audience. Engineers may want more detail about the data set, methodology, model, assumptions, and edge cases, often because they want that transparency from the start. A senior executive may need the conclusion, business impact, confidence level, and decision implication first. Audience matters because the same finding may require very different levels of explanation.
Good data communication also extends beyond words. The speaker’s pacing, emphasis, body language, and ability to respond to audience feedback can determine whether a technically sound explanation lands effectively.
Think of the story as the shortest route from evidence to a message people can act on.
What Is Data Science? A Clean Definition
Data science is the practice of using data, computational methods, statistical analysis, and domain knowledge to answer questions, discover patterns, make predictions, and support decisions.
Its toolkit can include:
- Programming: Python is widely used for data manipulation, machine learning, automation, and scientific computing. R remains important for statistical analysis and specialized research workflows.
- Data management: SQL is fundamental for querying and working with structured data, while tools such as pandas and NumPy support data manipulation and numerical analysis in Python.
- Statistics: Statistical methods help teams distinguish meaningful patterns from noise and quantify uncertainty.
- Machine learning: Machine learning models can classify, predict, rank, recommend, or detect patterns in data.
- Deep learning: Neural networks can handle complex problems involving language, image recognition, audio, and other high-dimensional data.
- Data visualization: Tools such as Matplotlib, Tableau, and Power BI help teams explore and communicate findings.
- Domain knowledge: Understanding the business or technical context helps determine which questions are worth asking and whether a result makes sense.
The most valuable data science work connects these capabilities rather than treating them as isolated technical disciplines.
A model’s value depends on the quality of the data, the question it addresses, the way its output is interpreted, and whether someone can use the result to make a better decision.
Python vs. R vs. SQL: Which Language Should Your Team Use in 2026?
There is no single programming language that makes a data science team effective.
Python is the broadest general-purpose choice for modern data science and AI work. Its ecosystem includes tools such as pandas, NumPy, scikit-learn, TensorFlow, PyTorch, and Matplotlib.
R remains valuable, particularly for statistical analysis, research, and specialized analytical workflows.
SQL is different from both. SQL is a data management language rather than a data science programming language, and it is essential for querying, joining, filtering, aggregating, and otherwise working with data stored in relational systems.
| Language | Strongest Use Cases | Role in a Modern Data Team |
| Python | Data manipulation, machine learning, AI, automation, scientific computing, visualization. | Broad general-purpose choice for data science and AI. |
| R | Statistical analysis, research, specialized visualization, statistical modeling. | Valuable for teams with strong statistical or research requirements. |
| SQL | Querying, joining, aggregating, transforming, and analyzing structured data. | Essential for accessing and working with production data. |
Python and SQL are strong baseline skills for many data teams, while R remains valuable for specialized statistical work. The right mix depends on the team’s data sources, existing systems, projects, analytical requirements, and the problems it needs to solve.
Pick the combination that lets the team work with its data and explain what it finds.
How Do Visuals Like Heat Maps Make Data Click for Nontechnical Audiences?
When you visualize data, make the important relationship easy to see. Clarity matters more than visual complexity.
Standard charts are often more effective than complicated custom graphics.
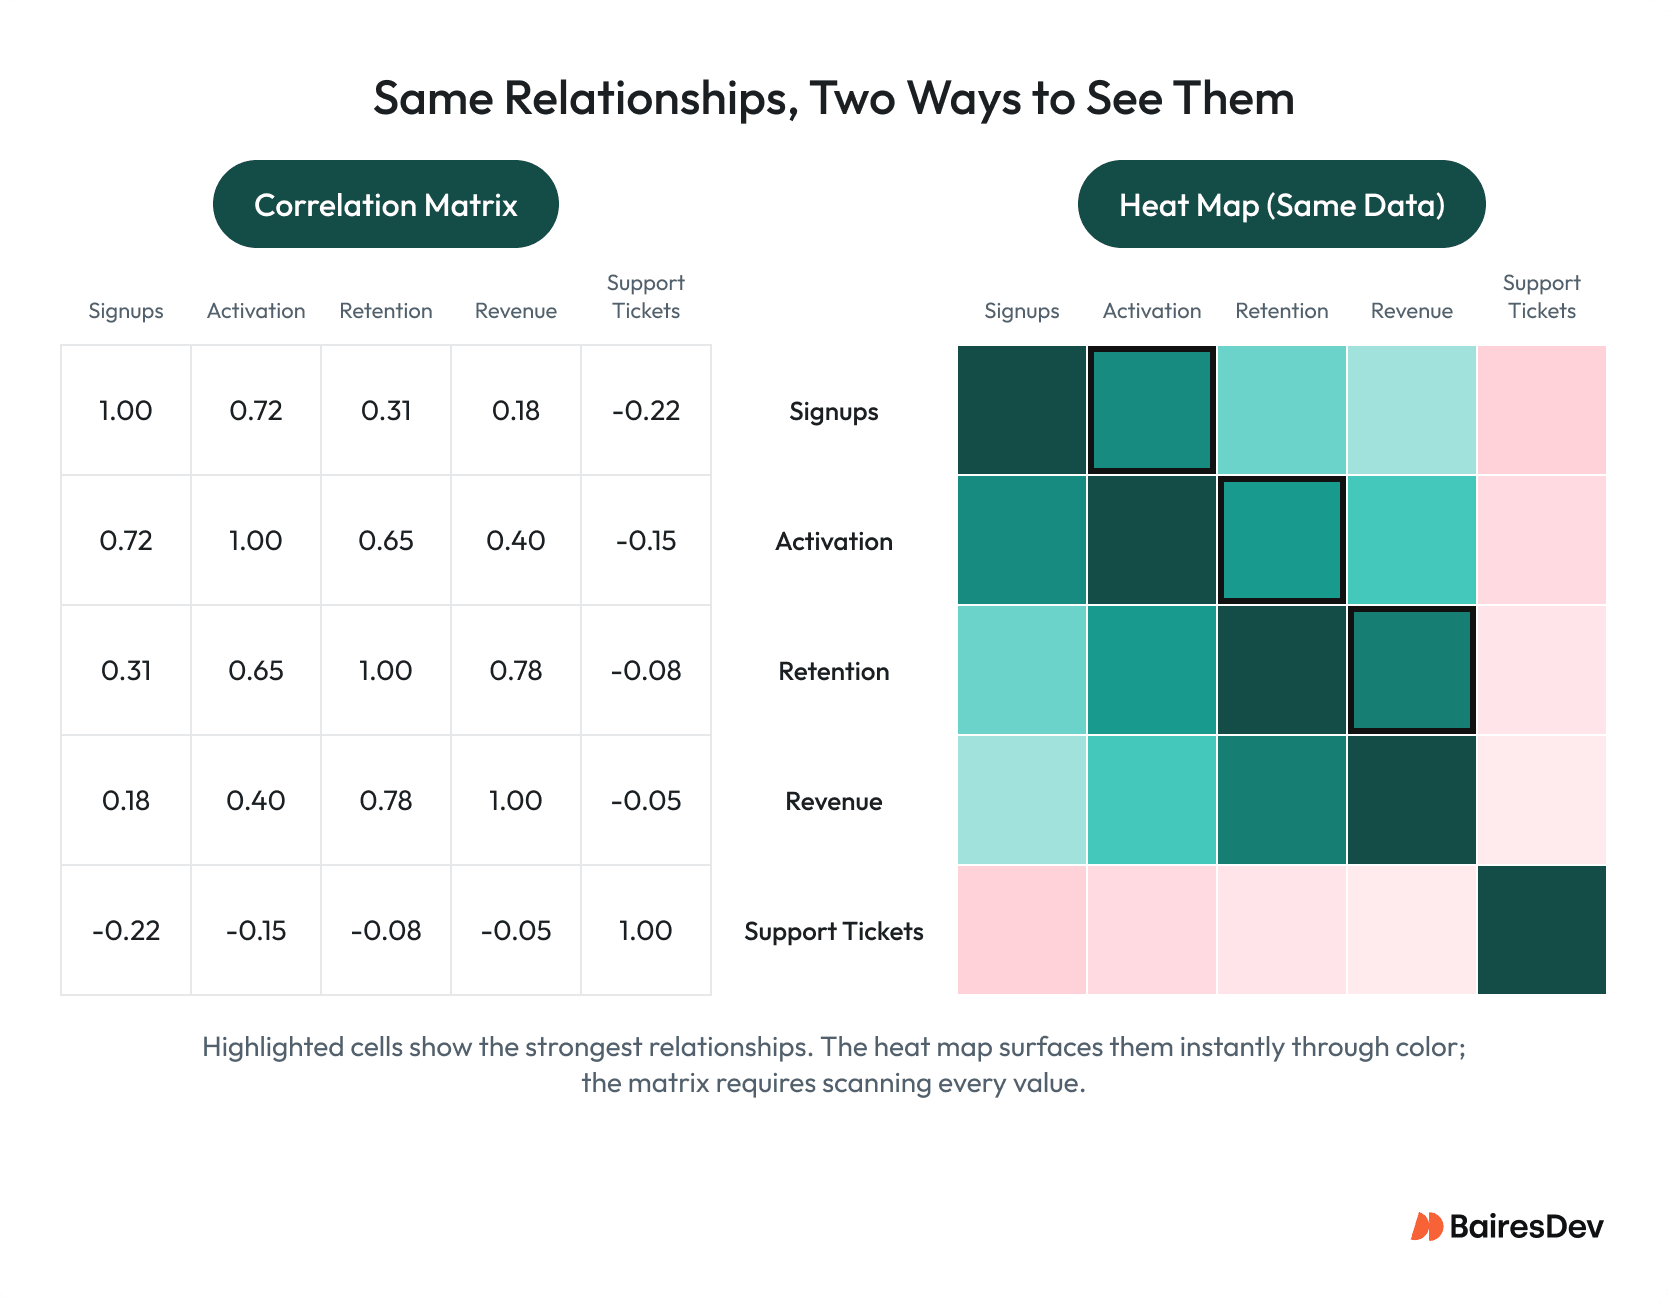
A correlation matrix provides a useful example. A matrix can show the numerical correlation between many variables, but a reader may need to scan each value to identify patterns. A heat map adds visual encoding so stronger and weaker relationships can be recognized more quickly, which makes patterns far easier to communicate to nontechnical audiences.
| Visualization | Best Used For | Main Advantage |
| Correlation matrix | Showing exact correlation values between many variables. | Preserves the underlying numerical relationships. |
| Heat map | Showing the same relationships through visual intensity. | Makes clusters and stronger patterns easier to spot quickly. |
The heat map contains the same information as the correlation matrix, presented so that patterns register faster.
Other charts follow the same logic. Use a line chart when change over time matters. Use a bar chart when comparing discrete categories. Use a scatter plot when examining relationships between two variables.
The familiar 10-20-30 presentation rule can also help keep visual communication focused: roughly 10 slides, 20 minutes, and a minimum 30-point font. It is a presentation guideline rather than a scientific law, but the underlying principle remains useful: remove visual clutter from every presentation and make the main point easy to see.
Can You Trust a Black Box Model You Cannot Fully Explain?
Sometimes, but not simply because the model is accurate. Some machine learning models are easier to interpret than others: a linear model can make its relationships relatively straightforward to inspect, while complex neural networks and ensemble models can be much harder to explain at the individual-prediction level. Even when a model provides useful signals such as feature importance, that does not necessarily explain why it produced a particular result.
This matters when the model influences consequential decisions. A model can perform well on a test set while still behaving poorly in a different environment over time. Data can shift, inputs can change, and a feature that correlated with the target during training may stop being useful later.
Model reliability therefore depends on more than predictive accuracy. Teams also need appropriate validation, monitoring, documentation, and an understanding of the conditions under which the model should and should not be trusted.
Simple models aren’t automatically right either. Simplicity can improve interpretability, but it doesn’t make a model correct.
The right question is not simply, “Can we explain every mathematical operation?”
A better question is, “Do we understand enough about this model’s behavior, limitations, inputs, and outputs to use it responsibly for this decision?”
How Does Explainable AI Help Solve the Black Box Problem?
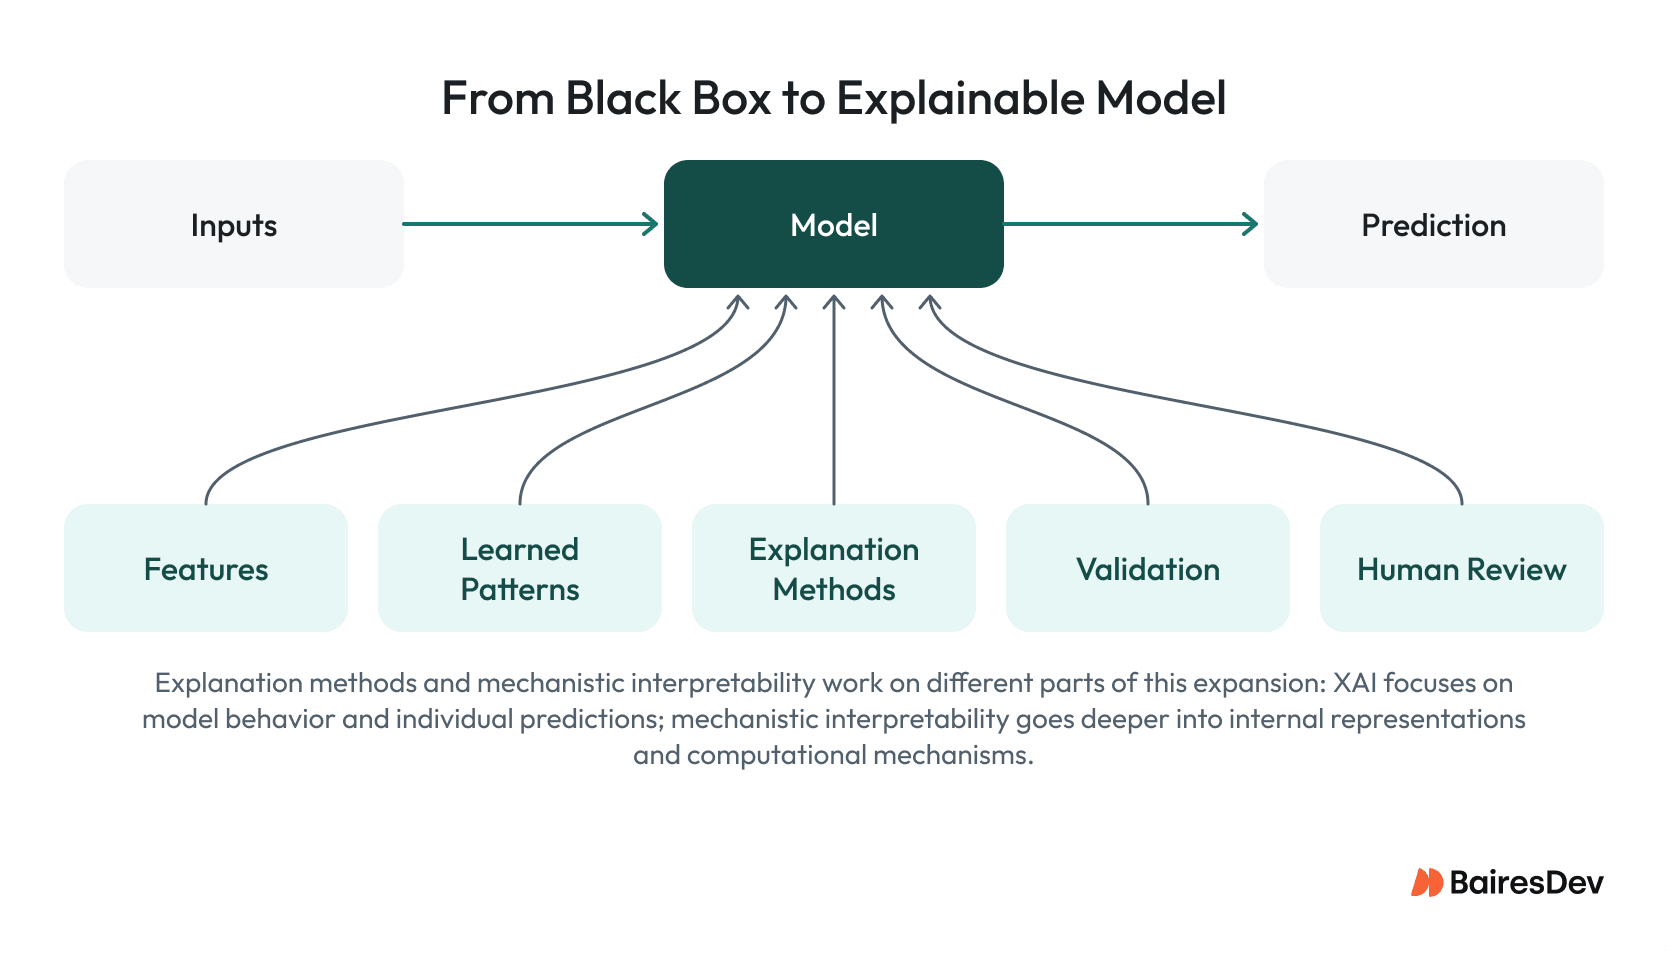
Explainable AI, or XAI, provides methods that help make model outputs easier to understand, evaluate, and challenge. Its importance has grown as organizations put increasingly complex models into production, particularly where transparency, accountability, bias, or regulatory requirements matter. Mechanistic interpretability is a related research direction that attempts to understand what happens inside complex models, but it should not be treated as synonymous with XAI. The distinction matters because the two approaches address different questions.
XAI generally focuses on making model behavior or individual predictions more understandable. Mechanistic interpretability goes deeper into the internal representations and computational mechanisms of complex models. Neither approach eliminates the need for sound data analysis. For engineering teams, explainability can help answer practical questions such as:
- Which inputs had the greatest influence on this prediction?
- Does the model behave differently across important groups?
- Are there obvious failure modes?
- Can a human reviewer challenge or override the result?
- What evidence should be retained for future investigation?
GPT-3 is also useful as a historical example of how quickly the field moves. The model was introduced in 2020 with 175 billion parameters, and its original technical paper documented the training approach and data mixture. One commonly repeated claim gets this story wrong: GPT-3 was not trained on 45 terabytes of filtered text. The 45 TB figure refers to the raw Common Crawl material before filtering; the filtered Common Crawl portion was roughly 570 GB.
The field also moves quickly. GPT-3, introduced in 2020, is now a historical example rather than a current model-generation reference. OpenAI’s deprecation documentation and the company’s announcement about retiring GPT-4o and older models illustrate how quickly prominent model generations can be superseded, a pattern any company building on third-party AI infrastructure should plan for. For engineering leaders, the practical lesson is to evaluate models, tools, and examples in their current context rather than treating yesterday’s leading system as today’s baseline.
Not every model has to be fully transparent. The level of explanation should match the model’s role, risk, and potential impact.
Why Does Explaining Your Methodology Build Trust in the Results?
A result without methodology is difficult to read or evaluate.
Data can be biased, incomplete, outdated, incorrectly collected, or interpreted outside the conditions in which it was produced. Even accurate data can lead to misleading conclusions when important variables are missing.
Explaining the methodology gives the audience a way to evaluate the result and feel free to challenge it constructively.
That explanation does not need to reproduce every line of code. It should provide enough context to answer questions such as:
- Where did the data come from?
- How was it collected?
- What was removed or transformed?
- Which assumptions were made?
- What statistical or machine learning methods were used?
- What limitations could affect the conclusion?
- What would cause the result to change?
This is particularly important when data is used to make decisions about customers or people. A model that appears objective can reproduce bias present in its training data or measurement process.
That distinction remains relevant even as data science tools become more sophisticated. The ability to build a model does not automatically create the ability to explain what the model means.
When Should You Use a Simple Model Instead of Deep Learning?
Model selection should match the problem, not maximize complexity. This is where the KISS principle, or “Keep It Simple, Stupid,” remains useful. If a simple regression model can answer the business question with acceptable accuracy and explainability, there may be little reason to introduce a much more complex architecture.
Complexity can increase:
- Development and maintenance requirements.
- Infrastructure costs.
- Debugging difficulty.
- Testing requirements.
- Explainability challenges.
- Dependence on specialized skills that are difficult to hire and retain.
Deep learning still earns its place. Neural networks are extremely useful for problems involving complex patterns in language, image processing, audio, and other data.
If a simpler model produces an adequate result, its transparency and lower operational burden may make it the better engineering decision. If the problem requires a more complex model to achieve the performance needed, the additional complexity can be justified.
Use as much sophistication as the problem needs and no more.
Should You Always Trust the Data Over Your Judgment?
No, not without applying judgment alongside it. Data is an important source of evidence, but it is not automatically correct or complete.
A data set can contain missing values, measurement errors, sampling problems, outdated information, or biases introduced during collection. A metric can also be technically accurate while failing to represent what the organization actually cares about.
Suppose customer satisfaction scores increase while customer retention falls. Neither number should simply be ignored. The discrepancy is a reason to investigate whether the metrics measure different aspects of the customer experience, whether the data was collected differently, or whether another factor explains the change.
This is where domain knowledge matters. A data scientist may identify a statistically meaningful pattern, but turning that pattern into a decision requires the broader team. A product manager may know that a major product change happened at exactly the same time. An engineer may recognize that an instrumentation change altered how events were recorded.
Those perspectives work together. Good decision making combines quantitative evidence with context and informed judgment, and that combination makes findings far more actionable than data alone. Make the reasoning explicit instead of treating intuition as unquestionable fact.
Where Does This Play Out in Practice?
The ability to speak data science matters anywhere technical findings have to influence a decision.
Product development
Teams can use behavioral data to identify friction, evaluate features, prioritize improvements, and measure whether changes produce the intended result.
Engineering operations
Engineering teams can apply data analytics to incidents, deployment patterns, system performance, and reliability data. The challenge is turning those measurements into decisions about architecture, testing, capacity, or process.
Customer analytics
Organizations can use data to identify customer segments, understand behavior, forecast demand, and evaluate retention. The methodology matters because customer data can easily produce misleading conclusions when context is missing.
Artificial intelligence
AI systems introduce an additional communication challenge. Stakeholders may understand the output without understanding its limitations, confidence, or failure modes.
In each case, the technical analysis is only part of the job. Someone has to translate the finding into a clear picture of what happened, why it matters, and what the organization should do next.
How Can Engineering Leaders Build This Skill Across a Team?
Speaking data science is a skill that improves through practice.
Teams can build that ability through a combination of theoretical knowledge, self-learning, hands-on experience, and repeated opportunities to explain findings to people with different levels of technical understanding.
Free online resources can provide a useful starting point. Khan Academy offers foundational material in mathematics and statistics. Stack Overflow can help developers learn from practical programming questions and solutions. Kaggle offers datasets, notebooks, and a data science community, and a Kaggle competition is a good way to work with real data.
The most useful learning path takes a hands-on approach, combining these resources with actual projects.
A practical progression might look like this:
- Learn the fundamentals. Build a working understanding of basic math, statistics, programming, and data analysis.
- Work with real datasets. Practice cleaning, manipulating, visualizing, and analyzing imperfect data rather than relying only on polished examples.
- Build small projects. Use Python, SQL, R, or another appropriate programming language to answer concrete questions.
- Explain the findings. Present the result to someone who did not perform the analysis.
- Ask for feedback. Find out which parts were unclear, overly technical, or missing important context.
- Repeat the process. The ability to explain complex concepts develops through practice just as technical skills do.
Nobody needs every engineer to become a data scientist. A team that understands data, questions assumptions, and can say what its analysis means is enough.
What Are the Key Takeaways From Speaking Data Science?
Programming languages, statistical analysis, and machine learning models are only part of data science.
The ability to communicate findings determines whether other people can understand the analysis, evaluate its limitations, and use it to make decisions.
The most effective data science communication has a few consistent characteristics:
- It starts with the decision or question that matters.
- It uses data as evidence rather than treating data as an unquestionable source of truth.
- It uses visualizations to make important patterns easier to see.
- It explains methodology and limitations clearly enough to establish trust.
- It matches the depth of the explanation to the audience.
- It favors appropriate complexity rather than maximum complexity.
- It connects technical findings to a clear action or decision.
Data science doesn’t end when the analysis is complete. The analysis gives you a chance to inform a decision, and communication is how you turn that chance into action.
Frequently Asked Questions
What does it mean to be data driven?
It means using accurate, timely, relevant data as your primary input rather than defaulting to intuition or habit. That doesn’t mean ignoring experience. It means combining judgment with evidence and testing your conclusions as new data arrives.
Why is communication the most important data science skill?
A technically accurate finding doesn’t change anything until someone acts on it. That only happens when stakeholders understand the result, trust the methodology and know what to do next. That’s why communication is as load-bearing as your statistics or your code.
What is a black box model?
It’s a model whose internal decision process is hard to inspect directly. Complex neural networks are the most common example, but interpretability varies across model types. A linear model is relatively easy to inspect. A large ensemble or deep network is much harder to explain at the level of any individual prediction.
How do you address the black box problem in 2026?
XAI and mechanistic interpretability are related but not the same thing. XAI helps you understand model behavior and individual predictions well enough to evaluate and challenge them. Mechanistic interpretability goes deeper into the internal representations and computational mechanisms of a model. Neither one replaces validation, monitoring and human review. Your team still needs all three regardless of which approach you’re using.
Is Python still the main data science language?
Yes. Python is still the broadest general-purpose choice for data science and AI. The ecosystem around it, including pandas, NumPy, scikit-learn, TensorFlow and PyTorch, is mature and widely supported. R stays useful if your team does heavy statistical or research work. SQL remains essential for anyone working with data in production systems.
How should I present data to executives?
Lead with the decision your data supports, not the methodology. The 10-20-30 rule is a useful structural check: roughly 10 slides, 20 minutes and a minimum 30-point font. Use visuals instead of raw numbers wherever you can. Include a brief methodology note so your audience knows why they can trust the result. Don’t bury it at the end.
What does it mean to speak data science?
It means translating your data, analysis and model output into a clear explanation of what happened, how confident you should be and what decision the evidence supports. That requires technical accuracy, audience-appropriate storytelling, useful visualizations and an honest account of your uncertainty and limitations. Done well, your audience can act on what you found.
What skills are required for data science?
The skills required for data science start with programming, statistics, data manipulation, SQL, data visualization, machine learning and domain knowledge. Communication belongs on that list too. If you can’t explain a finding to someone who didn’t run the analysis, the work doesn’t move decisions. That’s the practical test.
Rocío Belfiore is Chief Innovation Officer at BairesDev, where she leads teams developing internal software projects that propel company growth. She has been with BairesDev for over 11 years, advancing through engineering and R&D leadership roles.
Expertise