

Executive Summary
This article draws a distinction between two kinds of enterprise data. Type A is raw operational output from systems. Type B is the calculated business logic analysts build in spreadsheets, carrying intent and lineage at creation. Platforms capture Type A and ignore Type B, which is why business questions go unanswered.
When an executive leadership team asks a simple question, “What are the top new drivers of customer churn?,” most companies struggle to produce a precise answer in any reasonable amount of time. The business still falls back on spreadsheets, analyst-built workflows, and other decentralized tools.
Why can’t modern data lakes answer business-critical questions?
Data lakes capture operational data like events, transactions, and logs. The business logic that turns those records into answers gets built separately, by analysts working in spreadsheets, workflows, and departmental tools. That logic carries the definitions, lineage, exceptions, and intent behind the metrics leaders actually use, and most data platforms never see it.
That should be surprising, because by almost every other measure the industry has won the battles it set out to fight. Two decades into the Big Data era, Volume is solved. Petabyte-scale storage is available at commodity prices. Velocity is solved. Real-time streaming pipelines span the globe with built-in resilience. Variety is solved. We ingest, serialize, and persist almost any format a business produces. Query performance has improved alongside all three, with modern engines retrieving enormous datasets at speeds that would have seemed out of reach a decade ago.
Veracity arrived later as the fourth V, emphasizing trustworthiness, accuracy, and the confidence that the data in front of you is clean enough to act on. A large, mature tooling ecosystem grew up around exactly that promise: schema registries, streaming validation, real-time alerting, canonical data contracts enforced as messages arrive. Plenty of organizations that take data quality seriously have built genuinely impressive solutions here.
The fifth V is the one we still haven’t solved. Value.
We have built world-class high-speed rail for a city that is still hard to navigate. Bill Inmon, the father of data warehousing, warned years ago that without the right architecture, a data lake can become a place where data is stored rather than used. In the AI era, however, we have everything needed to make a next step towards democratizing data intelligence. Rather than only making stored data easier to interpret, we can capture business meaning much closer to where it is created.
Why Existing Data Approaches Haven’t Been Enough
Data Mesh
The industry’s most serious attempt to close that gap was Data Mesh. It proposed to decentralize ownership, let each business domain own and publish its own data products, and let insight scale the way microservices scale software engineering.
Data Mesh made an important diagnosis. Centralized data teams cannot keep pace with business context distributed across dozens of domains, each with its own definitions, edge cases, and priorities. The prescription is where it broke down. Making decentralized ownership real meant asking marketing, finance, and operations to each stand up their own data engineering function, which most of them had no budget, headcount, or mandate to do. Data Mesh asked every business unit to become a satellite IT team. Understandably, the quality of what they produced wasn’t consistent, and the whole idea got labeled “Data Mess.”
Data Governance Tooling
A substantial ecosystem of governance and quality frameworks was built in this space, making it possible to describe data definitions, enforce rules, validate streams, and establish enterprise-wide controls.
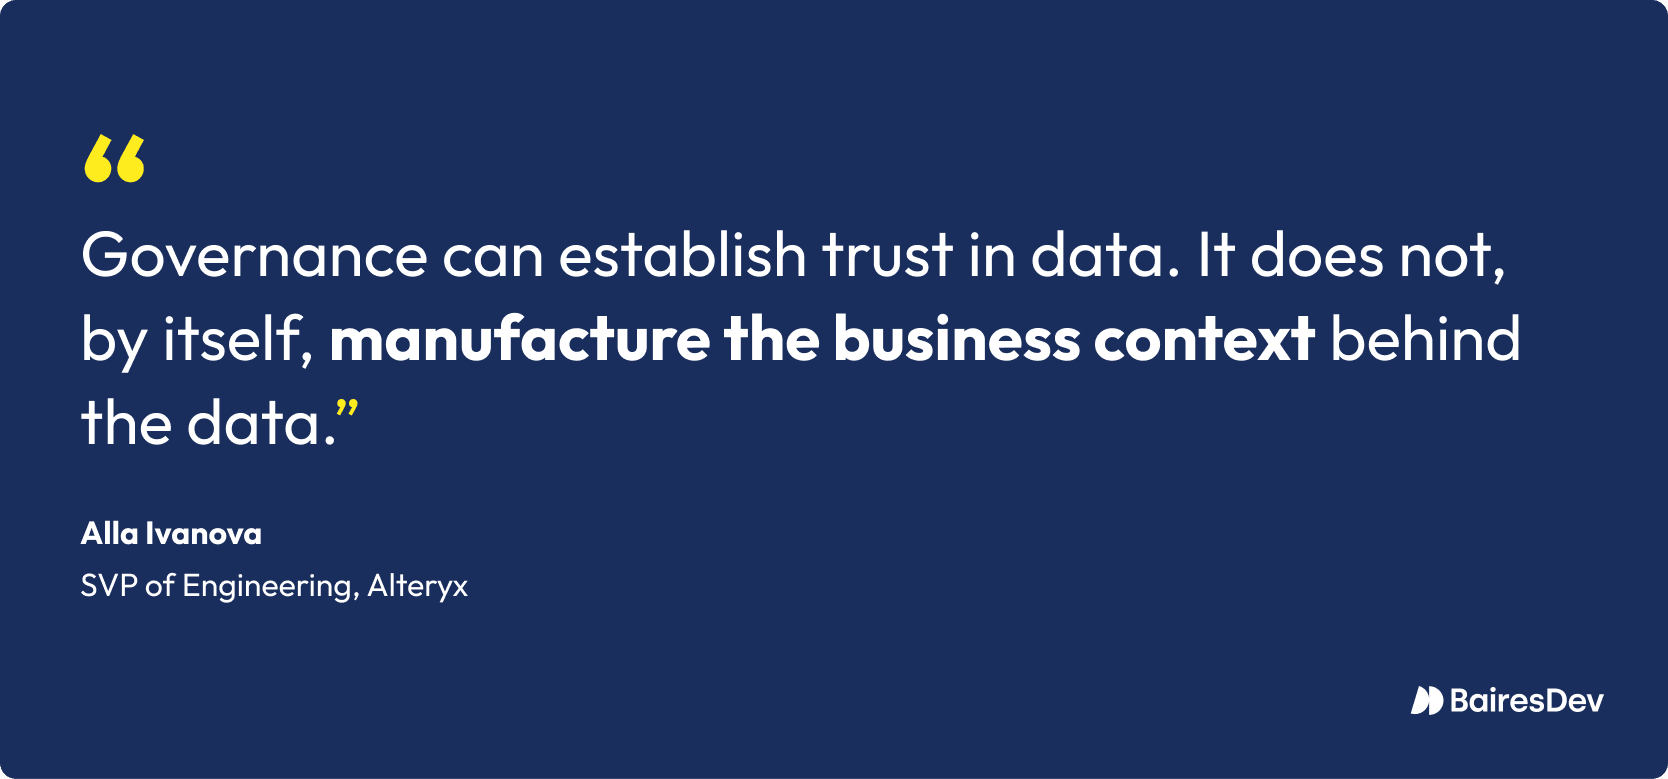
Some of these frameworks evolved into high-scale fault-tolerant streaming processors capable of detecting and alerting on malformed data in real time. They could tell you instantly that something was missing or wrong. What they could never tell you is why, or what to do about it. What happened next was always the same. Someone had to go find whoever understood that upstream system well enough to explain what changed and why. That investigation stays manual, human, and slow no matter how sophisticated the detection layer above it is. Governance can establish trust in data. It does not, by itself, manufacture the business context behind the data.
Metrics Stores
Metrics stores represented another important attempt to make business definitions explicit and reusable. The technical goal was compelling, aiming to define a metric once and make it consistent wherever it is consumed.
But the hardest part of a metric is not how to calculate it at scale. The biggest struggle companies faced is keeping those definitions current and fresh. dbt Labs’ Metrics Layer is a good example. It launched in 2022 with the promise of defining a business metric once, in code, and querying it consistently everywhere. By December 2023 it was deprecated, rebranded as “evolving into the Semantic Layer.” Some real problems got fixed in that transition, such as faster queries, better caching, and deeper tool integration. What it didn’t fix was the part that was never technical, pertaining to who owns a metric’s definition, who approves a change, and how conflicts between departments get resolved. Three years later, that’s still the exact gap the newest generation of these tools names as the top risk to getting this right.
I’ve watched this play out firsthand. RevOps and FinOps at my own company have genuinely disagreed on how to calculate “opportunities pipeline,” from which stages count as in pipeline, to whether early unqualified opportunities belong in the number, to how aggressively to weight by probability. I saw versions of similar arguments at Groupon and at Uber. Neither side is wrong. They are optimizing for different questions, because leadership wants a growth signal and RevOps wants a number it can defend to the board. Which suggests the goal may not be forcing convergence on a single definition at all. The harder and more useful problem is supporting multiple versions of the same metric concurrently, each with its owner and its purpose attached.
Semantic Layers
The AI era has brought a new wave of semantic layers, metadata catalogs, YAML-based modeling frameworks, and “golden query” repositories. These approaches are genuinely useful. LLMs need reliable definitions and context if they are going to reason over enterprise data.
But there is a fundamental question beneath the annotation problem. Who actually populates and maintains the enterprise semantic layer? Who understands the data well enough to do that job, and how far are they from the process that created it?
Consider how Glean works. It does not require an organization to manually recreate its knowledge in a new knowledge base before that knowledge can be searched. It connects to where the knowledge already lives, in Slack, Confluence, Google Drive, and email, and indexes it for consumption.
A semantic layer built purely on top of a data lake faces the opposite challenge. It has to reconstruct human intent from data after ingestion has already stripped away the business context, sometimes long after the people who understood that data have moved teams or left the company.
All of these approaches are needed for trustworthy enterprise-wide data intelligence. They are just not sufficient on their own. The AI era has opened up an opportunity for the next level of capability.
The Missing Piece Is Already There
Consider where many of the answers to mission-critical business questions actually come from. Marketing teams build campaign-attribution models. Finance reconciles revenue. Sales teams calculate pipeline and commissions. Operations teams maintain churn trackers. Analysts build recurring workflows that combine sources, apply business rules, and produce metrics that people trust enough to run the business on.
These artifacts are often dismissed as “shadow IT.” Some deserve that label. But there is another way to look at them. They are business-critical data-producing systems.
The key distinction is between two kinds of data entering the enterprise data platform.
Type A: Operational Data
This is what the industry has spent twenty years building infrastructure for, the clickstreams and event logs and transactional records that systems generate on their own. It’s high-volume and, critically, meaningless until someone downstream interprets it. A clickstream fact tells us that something happened. It does not tell us what that event means to this particular business, how it should affect a metric, or which business definition should govern its interpretation.
Type B: Business-Meaning Data
This is the calculated, business-critical metrics and logic that come out of the tools business departments use every day to do their jobs. Type B data carries human business intent, lineage, and semantics at the moment it’s created, instead of being pieced back together later. Someone builds that customer churn or opportunities pipeline or sales commissions calculation every month because the business can’t run without it. Someone chooses that join, that filter, that specific definition of “active customer.” It is all happening in marketing’s campaign attribution spreadsheet, finance’s revenue reconciliation workflow, in analyst-built workflows in tools like Alteryx, and in the operations churn tracker somebody built eighteen months ago that the team still trusts more than the official dashboard.
Two Kinds of Data Entering the Enterprise Platform
| Type A: Operational Data | Type B: Business-Meaning Data | |
| What it is | Raw events and records generated by systems | Calculated metrics and logic produced by people |
| Where it comes from | Clickstreams, transactional databases, event logs, application data | Spreadsheets, analyst-built workflows, departmental tools – all joining various data sources including databases, files, API getaways |
| Who creates it | Systems, automatically | Business analysts, as part of their day job |
| What it carries | A record that something happened | Business intent, lineage, and semantics, captured as the metric is built |
| Volume | High | Low |
| Business context | Added downstream, by someone reconstructing intent | Present at the moment of creation |
| Relationship | Can feed Type B | Can use Type A, but also depends on sources, rules, and exceptions the data warehouse never sees |
None of this argues that Type B replaces Type A. Type B can answer a surprisingly large share of mission-critical business questions, because businesses have already invested in the people and processes that produce those metrics. That makes it a source worth bringing into the central data platform as a Certified Metric, carrying metadata created by the people who actually understand what the metric means.
With Type B feeding the central data lake and its semantic layers, the data warehouse becomes something that self-maintains. Type B flows in continuously alongside Type A, carrying its context, and the insights become available across the whole organization.
This is exactly where metrics stores adoption hit the obstacles. Organizations were not able to converge this idea with the Data Mesh approach and use business analysts as certified metrics producers. The definitions and calculations those analysts build every day, week, and month are exactly what metrics stores need, generated as a side effect of doing their job rather than as a separate initiative someone has to staff, fund, and maintain.
How AI Changes the Business-Meaning Problem
What’s changed in the AI era is that we now have the ability to capture a business metric and its metadata without a data engineer in the loop. This means the Data Mesh dream can finally become a reality. A system can promote the certified metric into a metrics store and send AI-ready workflow metadata to the semantic layer, describing what the metric computes, why, and what it depends on. Alteryx is one example. The cost of decentralizing comes down to something business departments can actually absorb.
Building a semantic model has always required two people, one who understands the business and one who can encode that understanding technically. The second person has always been the bottleneck, because judgment has to be translated from one person to another, and something gets lost in that handoff.
The argument now is that AI coding agents can take over the encoder’s role. Point one at a public ecommerce dataset and it will do what a competent analyst does before trusting anything, establishing the grain and testing every join. What the agent cannot do is decide what revenue means in this particular company, and that maps directly onto the distinction between Type A and Type B data. The agent automates the encoding. It does nothing to remove the need for judgment. If anything, it raises the stakes on getting that judgment right, because the resulting definition now gets applied instantly and at scale, instead of waiting for someone to notice an error.
We need to flip the script and model the business meaning first, then publish it for consumption by people and AI agents. Concretely, that means four things.
1. Capture at the Source
Instrument the tools where Type B data is created, the workflows and the spreadsheets, so both the calculated metric and its metadata are captured the moment someone defines a metric, rather than months later by someone trying to reconstruct it. The calculated outputs should feed the metrics store while the metadata flows into the lake’s semantic layer.
2. Make Capture a Side Effect
Data Mesh asked business teams to become data engineers, and that is why it stalled. Nobody should have to do extra work to productize their spreadsheet. The person building this month’s churn calculation is already producing the metric, and the system’s job is to capture it without adding a deliverable to their plate.
3. Define AI-Assisted Metrics Ownership and Governance
Similar to how AI software development now works through observability and alerting across the lifecycle, organizations need a way to use AI across the metrics governance cycle. Ownership should attach to each definition rather than to the metric name, so two departments can hold competing versions of “pipeline” without either being wrong. AI can then detect and alert on changes, conflicts, and anomalies.
4. Feed It Back Continuously
Type B data isn’t a batch job to run once. It has to flow into the lake alongside Type A on an ongoing basis, so the semantic layer stays current as the business itself changes.
What Still Has to Be Solved in Enterprise Data
Getting Type B data flowing into the enterprise data warehouse at scale, along with AI-ready metadata, is an infrastructure and orchestration problem as much as a modeling one. How do you instrument thousands of workflows and spreadsheets without disrupting the people who rely on them daily? How do you keep that lineage current as the underlying work evolves? And once AI agents are reasoning over this newly surfaced institutional knowledge, how do you orchestrate them reliably across the whole enterprise?
I can’t point to anywhere this is solved end to end, including my own company, where business departments already push their workflow outputs into our enterprise warehouse but not yet the metadata that explains them. Three obstacles stand out.
Business logic doesn’t live in one format. It’s scattered across spreadsheets, Alteryx workflows, and BI dashboard definitions, and an encoder has to speak all of them.
There’s a cold-start problem. Someone still has to build the initial knowledge base, and today that means a bespoke migration path for every source. Migrating even one tool’s definitions is substantial work.
A trustworthy encoder has to behave like a governance system wired into source control. What triggers a “definition changed” event? How does a new definition get tested and rolled out without breaking every report built on the old one?
That’s the work worth doing next. A smarter catalog was never the prize. The prize is AI-ready certified metrics and golden-tier OLAP cubes that arrive as a side effect of running the business, rather than as the output of central data engineering detective work.
Key Takeaways
- Volume, velocity, variety, and veracity are largely solved. Value, the fifth V, is the one enterprise data platforms still can’t deliver.
- Data Mesh got the diagnosis right, then asked marketing and finance to run their own data engineering function.
- The metrics a business actually runs on already exist, rebuilt on a regular cadence by analysts in spreadsheets and other departmental tools that carry the intent behind them.
- An AI agent can encode a semantic model now, but deciding what revenue means at a given company is still human work, and the stakes are higher because the answer propagates instantly.
- Ownership should attach to each metric definition rather than the metric name, so two departments can hold competing versions of pipeline without either being wrong.